Why Identification Matters: Changing How We Think About MMM
Identification is all about teasing out real causal relationships between tactics and outcomes — and it's the backbone of Haus’ Causal MMM.
Nov 11, 2025

At Haus, we’re obsessed with getting to the truth — the real causal story. That's why we're determined to evolve industry thinking when it comes to one key piece of marketing mix models (MMM): Identification.
Identification is about teasing out (or, uh, identifying) an actual, real causal relationship between tactics and outcomes. Identification goes beyond looking for patterns and trends and allows you to confidently say, “That is the actual effect.”
Identification is particularly important in MMM because when you can clearly identify the impact of one channel, it makes it easier to more accurately measure the impact of the others. And once you can correctly measure the impact of channel spend on your KPIs, you can more effectively use your MMM to guide ad spend decisions.
I’ll dive into all of that in a bit more depth. But before we go any further, a bit of history. Because generations of economists have dealt with the issue of identification and correlation vs. causation.
A (very) short history of identification
Let’s rewind to the early 1900s. At Yale, a group called the Cowles Foundation wanted to estimate customer demand. Their logic was simple: when the price goes up, people buy less; when price goes down, they buy more. So they plotted prices and quantities on a graph and tried to draw a demand curve.
But when they looked at the data — just a cloud of dots — they knew they had a problem. Sure, they could fit a line through it. But were they estimating a demand curve or a supply curve? After all, supply curves go through prices and quantities, too, but in the exact opposite direction (firms are more excited to sell stuff if they can charge more). Both demand and supply curves trace a pattern between price and quantity — one sloping down, the other sloping up.
The Cowles Foundation found that, actually, just fitting a line through a market’s price/quantity data wouldn’t actually give you either demand or supply! That’s because we’re not just seeing how behavior changes because of price. We’re actually seeing the outcome of lots of interactions between consumers and producers, each responding to prices in their own ways, resulting in the outcomes we see in the data.
In other words, neither supply or demand were identified.
This work in identifying supply and demand kicked off a whole new discipline of econometrics focused on one profound truth: You can’t just look at patterns in the data and assume you’ve identified cause and effect.
MMMs and the “Just Stuff” Problem
Fast-forward a hundred years to MMMs. Identification is just as big of a problem for modern MMM practitioners as it was for the Cowles Foundation, and for a similar reason: MMM data is terrible.
Take peak season, for instance. During that time, organic demand is up. This means your KPI (e.g. sales) is also up. But you’ve also increased ad spend. So…everything is going up at the same time. When you feed that into a model, what are you actually learning? You’re seeing the pattern that everything is going up, but you don’t know which tactics are causing which outcomes. We can’t be sure that the channel impact is identified.
The Cowles Foundation used a combination of better data and model understanding to identify supply and demand. We do the same for MMMs, but we use the gold standard data for causal identification in marketing measurement: Incrementality experiments.
Incrementality experiments + MMM = Identification
A recent survey from Kantar shows that 51% of teams are using an MMM alongside attribution and experiments. That’s great, but one of the most common questions we get at Haus is:
“Our MMM says one thing, but our experiments say another. What gives?”
People justify these differences by saying the methods are estimating different things and then use “triangulation” to mix and match results across methods to try to make a cohesive story. But the real issue that triangulation ignores is that disagreement between MMMs and incrementality tests is actually an indicator that the MMM probably isn’t actually identified.
Now, this isn’t to say that you can’t learn more from an MMM than an experiment by itself. Done well, MMMs provide a comprehensive view of your marketing activities, special events, lagged effects, and more. They give broader insight into the impact of marginal spend changes across a range of marketing channel spends, supporting KPI forecasting and budget optimization. However, there are parts of your MMM that should always align with your incrementality experiments. If they don’t, something in the model isn’t properly identified. It’s not finding true cause and effect — it’s just chasing correlations.
Identification issues usually happen because MMMs don’t take experiments seriously enough. For instance, the standard Bayesian approach would say, ‘Here's the experiment, here's your return curve based on observational data. Let’s start pulling the return curve toward what the experiment tells us.’ You’re essentially nudging your model toward the results of your experiment, which gets closer to ground truth, but doesn’t fully identify the return curve (which in turn means that other channels’ return curves aren’t identified, either)
Or they’re using a frequentist approach, which starts by finding the thousands of models that do just as well at predicting out-of-sample KPIs. Then they narrow the list down by focusing on the models that seem more in line with your experiments. But these still aren’t identified, since that usually only narrows it down to a few hundred models.
In both cases, you’re saying, ‘Hey, here's some general guidance, let's kind of try to bound our model around here.’ But in both cases, experiments are treated as suggestions that don’t quite get to identification. Haus takes it a step further.
How incrementality experiments drive identification in Causal MMM
We know experiments are the closest we can get to estimating the ground truth impact of your marketing spend on a channel. And if that's the case, then we don't just want these experiments to be suggestive. We want them to be the starting point of our model.
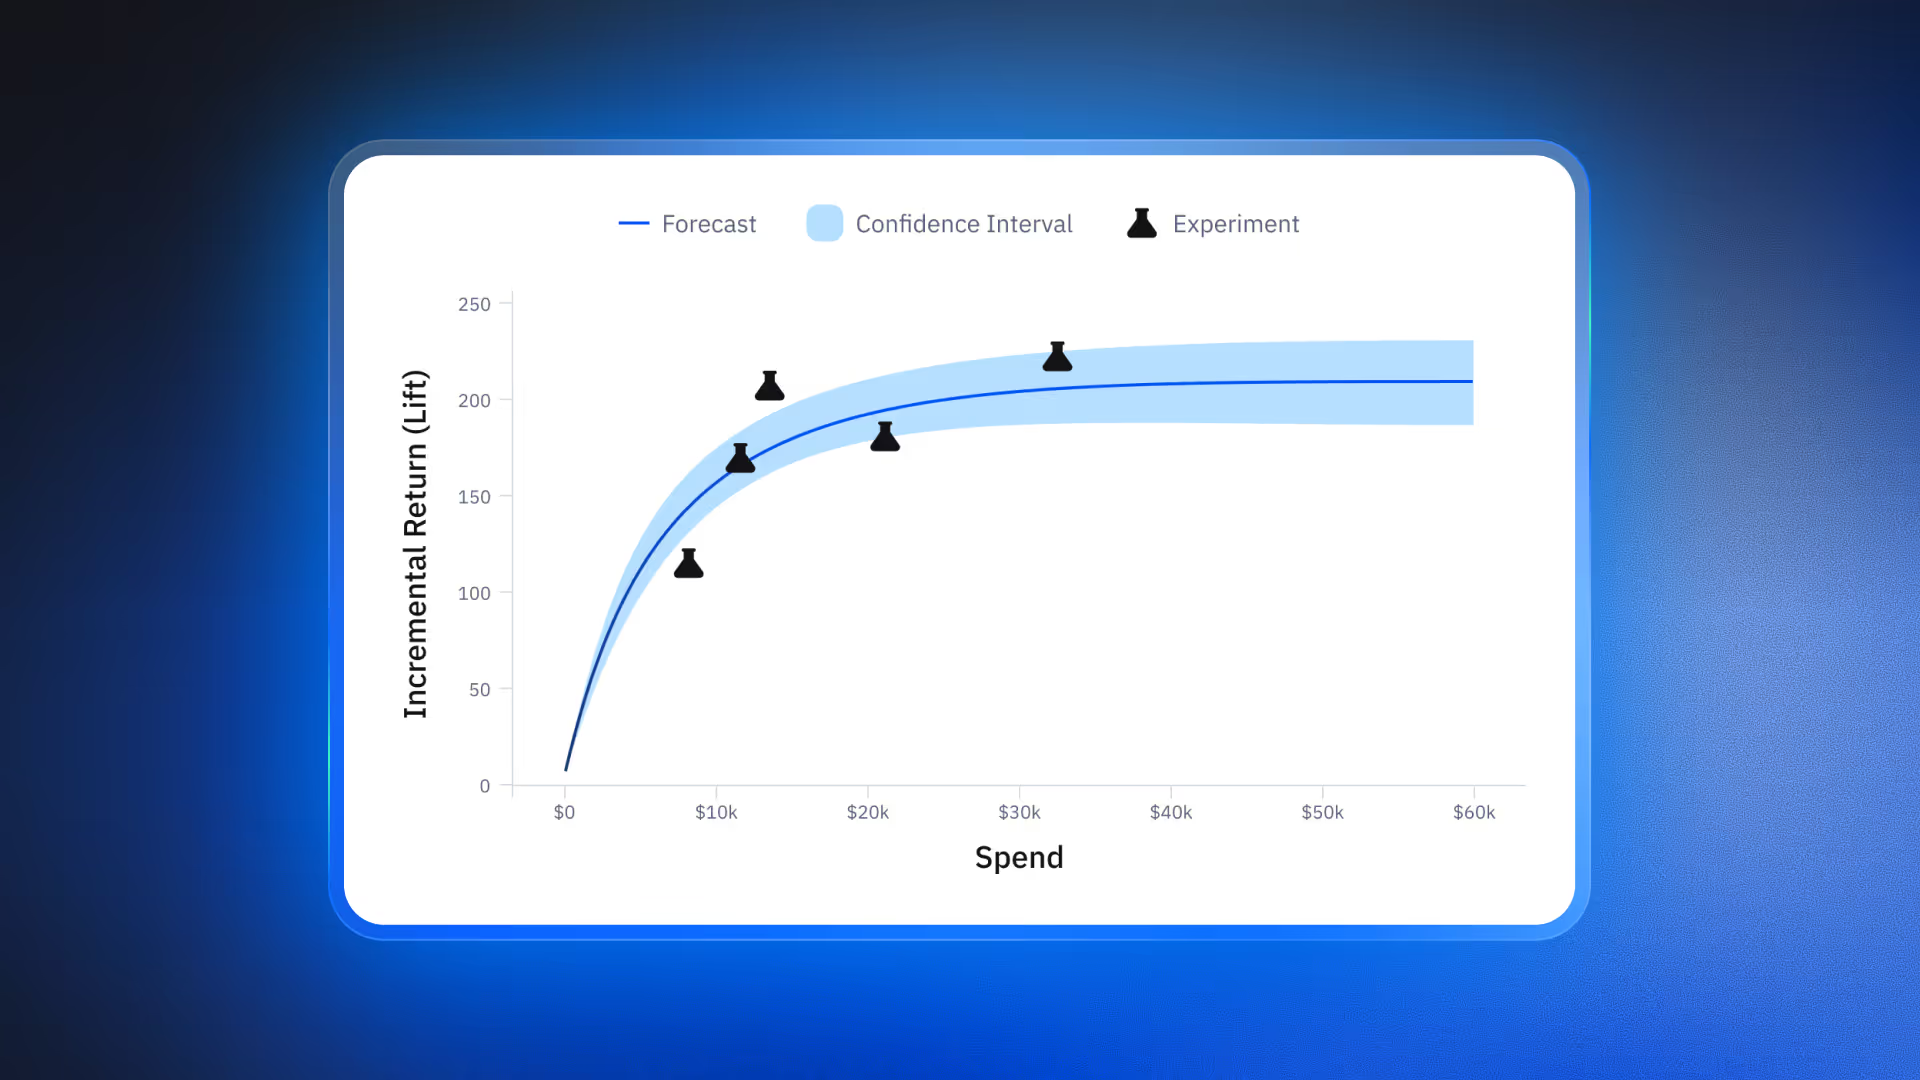
Say you’ve run an experiment and found that Channel A has a real, causal effect on your KPI. That’s an identifying data point. It might be noisy, sure, but it’s real. You’ve isolated an unbiased estimate of how spend on Channel A impacts your primary KPI under specific conditions.
Using a proprietary algorithm that extends the standard Bayesian approach, when you estimate your model with the Haus, you can anchor to that result. The Haus Causal MMM knows that — for the part of the model that represents the conditions of your experiment — model incrementality equals experimental incrementality. And at that point, the model is identified.
Identifying the impact of Channel A means there is less variance left over in your KPI for the model to explain, making it easier to identify the impact of Channel B, too. But if Channel A wasn’t nailed down properly? Everything downstream gets fuzzy. You’re not actually identifying the impact of Channel A or Channel B — you’re just trying to explain partial “leftover” effects.
But once that first point is solid, the fog starts to lift. Each new anchor point of identification reduces uncertainty. Less noise. Less confounding. Better overall identification, even for channels you haven’t tested yet.
The future of MMM is causal
From that same Kantar survey, we learned that 37% of respondents struggle to “accurately understand impact on ROI for key campaign performance drivers.” That’s because, as we said, MMM data isn’t great. It’s full of collinearity. This makes it hard to identify causal effects. Which makes it hard to act on.
Experiment-based identification is the solution to these long-standing pain points. Because when you’ve identified impact, everything changes. You’ve gone from modeling what happened to uncovering why it happened.
That’s the future of MMM — a future where teams can actually tie ROI to campaigns. And it starts with one simple but powerful shift: Stop chasing patterns. Start chasing identification.
Subscribe to our newsletter
Article tags
Article authors

Phil is the Head of Science Strategy at Haus, leading the company's scientific direction and R&D roadmap. He previously led scaled causal modeling at Amazon, advising executives and supporting over $1 billion in annual investments. A PhD in Economics, Phil has spent his career researching and teaching econometrics and data science across academia and industry.