The Good, The Bad, and the Ugly of Building In-House MMM
Haus' Senior Applied Scientist Ittai Shacham has built in-house MMM — so he's seen how the early promise of in-house MMM can slowly fade away as trust erodes.
Sep 23, 2026

Yes. It’s true. I admit it: I have built an in-house MMM. No measurement partner, no data science team, no consultant to interpret results. So I know it’s possible, but I also know where it fell apart.
And that’s the very reason I’m at Haus: I’ve built in-house MMM, which has made me a believer in the need for something like Haus.
When I gather my Haus coworkers around the campfire to tell them the scary story of building an in-house MMM (not actually, but stick with me here), they’re usually surprised at how the in-house MMM story tends to unfold. It often starts out good, slowly gets bad, then quickly gets ugly. In that order.
The starting point is often the same: Teams build in-house MMM because they’ve been burned by a vendor. This vendor’s MMM output was underwhelming — it was slow, it was unexplainable, it didn’t align with other day-to-day sources brands rely on, and was therefore hard to be confident to use for decision-making.
So, they hire some engineers and build an MMM internally. Should be easy enough in the world of AI and open-source options, right?
The deceptively easy path to in-house MMM
For many well-resourced enterprise companies, building an in-house MMM is as easy as 1-2-3: one open-source model, two data scientists, and maybe three engineers to manage it. Boom, you have an in-house MMM and a team to manage it.
With all these off-the-shelf MMM tools like Robyn and PyMC, going from zero to one is no sweat. This small team can get a model running, generate response curves, and produce charts in a matter of weeks. The first wins come quickly.
“Finally!” they say. “We have some control. No more dealing with noisy, useless inputs from some vendor who knows nothing about how our business operates.” The decision to move in-house seems validated. They would’ve waited months to get to the same point through a traditional vendor.
But this early success is precisely what makes the next phase so difficult.
Month 1: The honeymoon phase
The dangerous moment in an in-house MMM isn’t when it fails. It’s when it works just well enough to convince everyone they should continue managing the MMM themselves. That’s when things get wasteful, frustrating, and a drain on the business.
First, the team gets results quickly. Sure, they notice a few questionable results and discrepancies around the edges, but that’s okay. They built this in a month. “Think of what we can do from here!” they say.
But it’s the next step — getting genuinely actionable outputs that they’re confident in — that becomes much harder with a small in-house MMM team.
Months 2–4: The cracks begin to show
By months two through four, teams start thinking, “Great, we got results. Let’s start using them.” But that’s when the discrepancies really begin to surface.
They realize the MTA says something completely different from the MMM. And the MMM isn’t consistent with the team’s experiment results. Meanwhile, the channel rankings are different. Nothing is lining up. When they try to reconcile different results, they start seeing the cracks.
The response is usually, “It’s new. We’re still building it out.”
Then the months go by. By month four, the pressure from above starts to accumulate. The team needs to provide results. “Have you fixed it yet?”
Months 4–6: The tuning trap
Around this point, they find the lever. They realize the Bayesian model can be manipulated through its priors. They learn how to adjust them, and suddenly they have a way to make the results look more plausible — or more like what the business expects to see.
Is the pressure building because the team is trying to act on the data and not getting the expected results? Or because what they thought was fine-tuning turns out to be much more involved? Probably both.
Eventually, they find the pressure point: prior tuning.
And prior tuning is essentially cherry-picking. It means choosing how the model should start in order to get the results you want to see in the end.
The implication is clear: you’re picking the results that line up with your answers.
There will always be something you can play with in a model to get a different result. It’s not specific to a Bayesian model; any model has levers. And wherever that lever exists, people will eventually pull it. Unfortunately, that has consequences.
Months 6–12: Chipping away at credibility
Six months in, the model is working. Or at least, it seems to be.
Then the cracks show again. They always do.
Maybe next month, MTA shows an efficiency increase in a particular channel, but the MMM doesn’t. Maybe an experiment shows the same improvement — perhaps with different numbers — but the MMM says something completely different.
This is where confidence starts to erode.
At that point, the company has two choices. It can go all in on building the infrastructure and hiring the resources required to get the model on track. That means maintaining a team whose job is, in part, to keep adjusting the model. Or it can pay an outside provider.
That’s the decision point that usually arrives around month twelve. The model may never be trusted fully unless the company is willing to spend millions building and maintaining the entire system.
And even if you build it, keeping it up to date is a continuous investment. Think about the amount of work required to make the model better, more reliable, and more useful over time.
The need for an integrated system
I’ve done a lot of complaining so far. It’s about time for me to suggest a solution.
And here is where you roll your eyes. Because you’re going to see I’m an economist at Haus. And you’re bracing yourself. Because I’m about to say…the solution, my friends, is Haus.
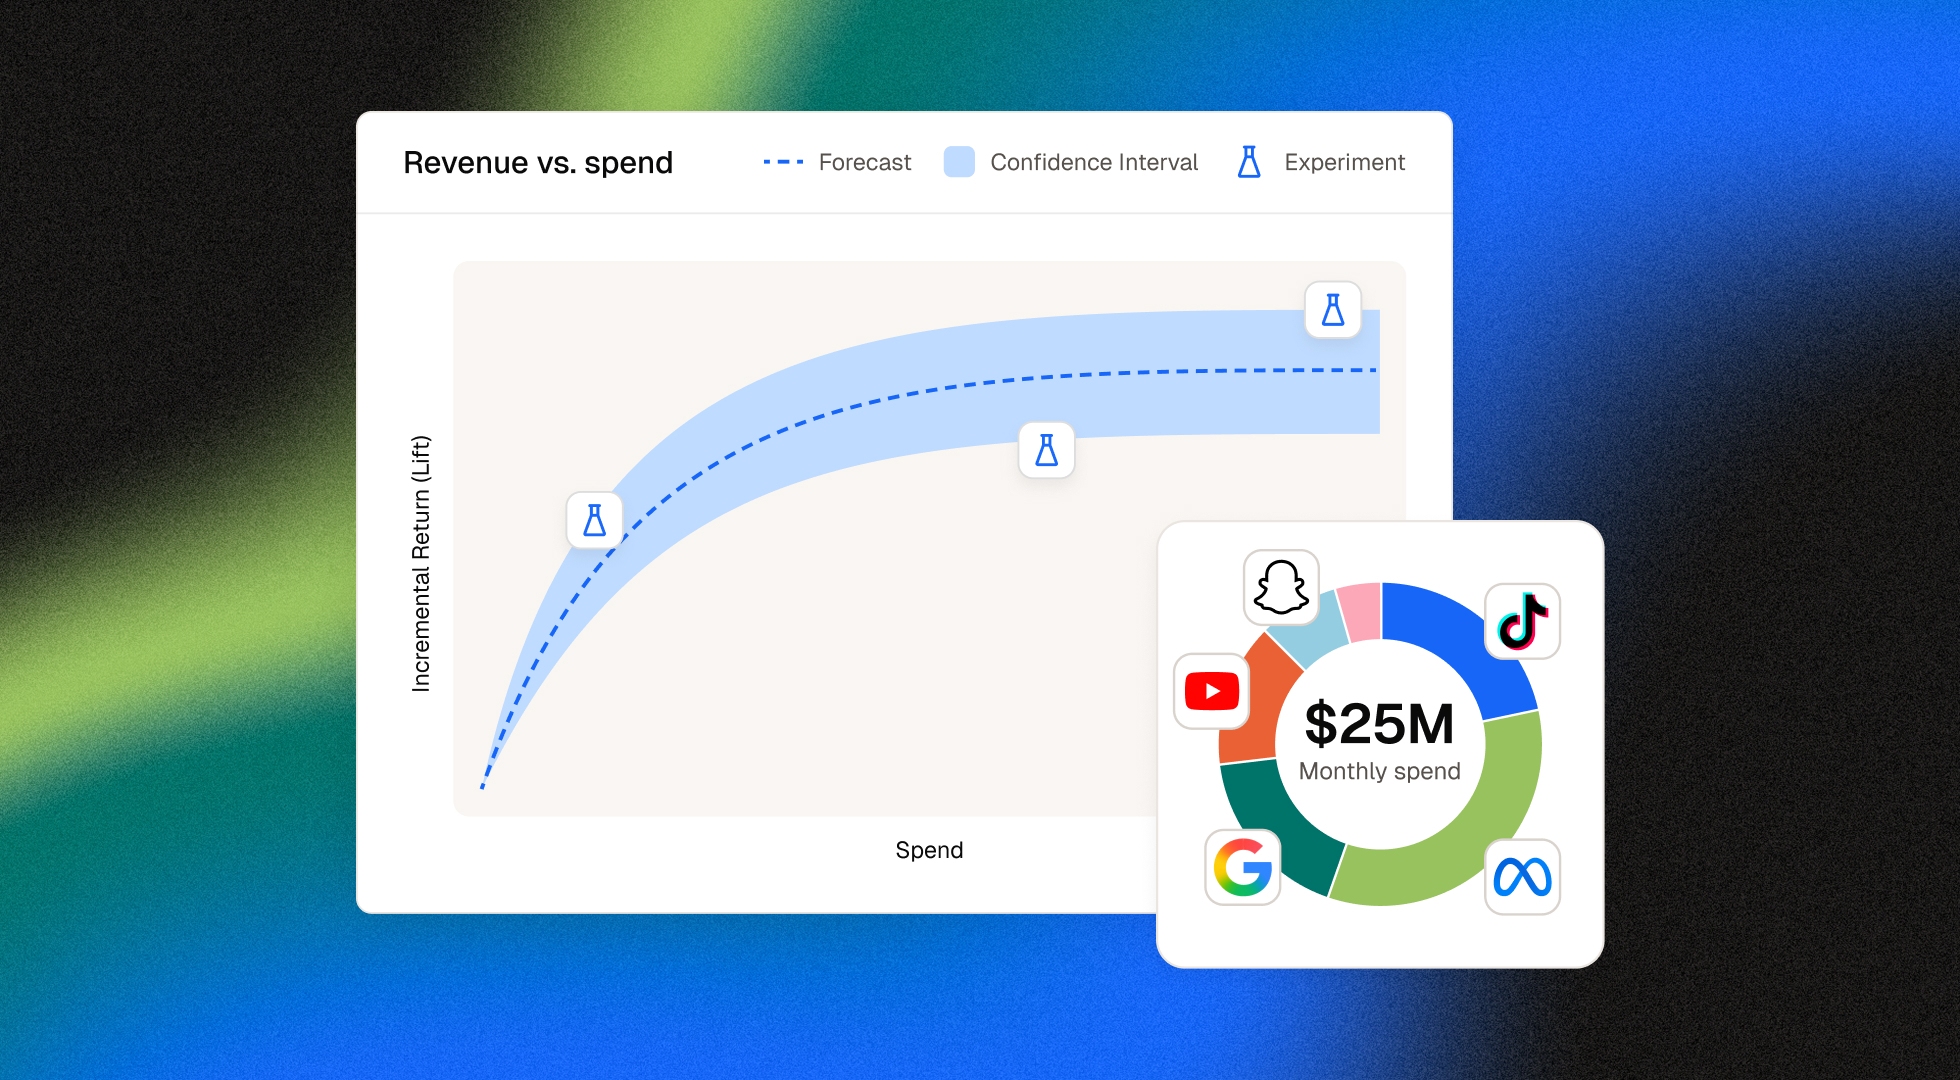
Don’t worry. I’m not going to do that. Instead, I’m going to give you a general sense of what a strong MMM looks like. Yes, I believe a causality-driven MMM is the best way forward. Yes, I think your MMM needs to be tuned by experiment results. Those beliefs are coming from my experience building an MMM and identifying what would’ve solved the challenges I ran up against.
But I’m going to keep things more general and hopefully more helpful for you, the data scientist or engineer, who is hoping to get buy-in for a vendor that actually supports you and makes your life easier.
The dream-state in 2026 is an integrated system where the parts of your measurement system “talk to each other” in order to provide a robust and coherent signal. It automates simple tasks so that you can spend more time on deep data-driven work. (Faith Shin from Wayfair describes that ideal state well here.)
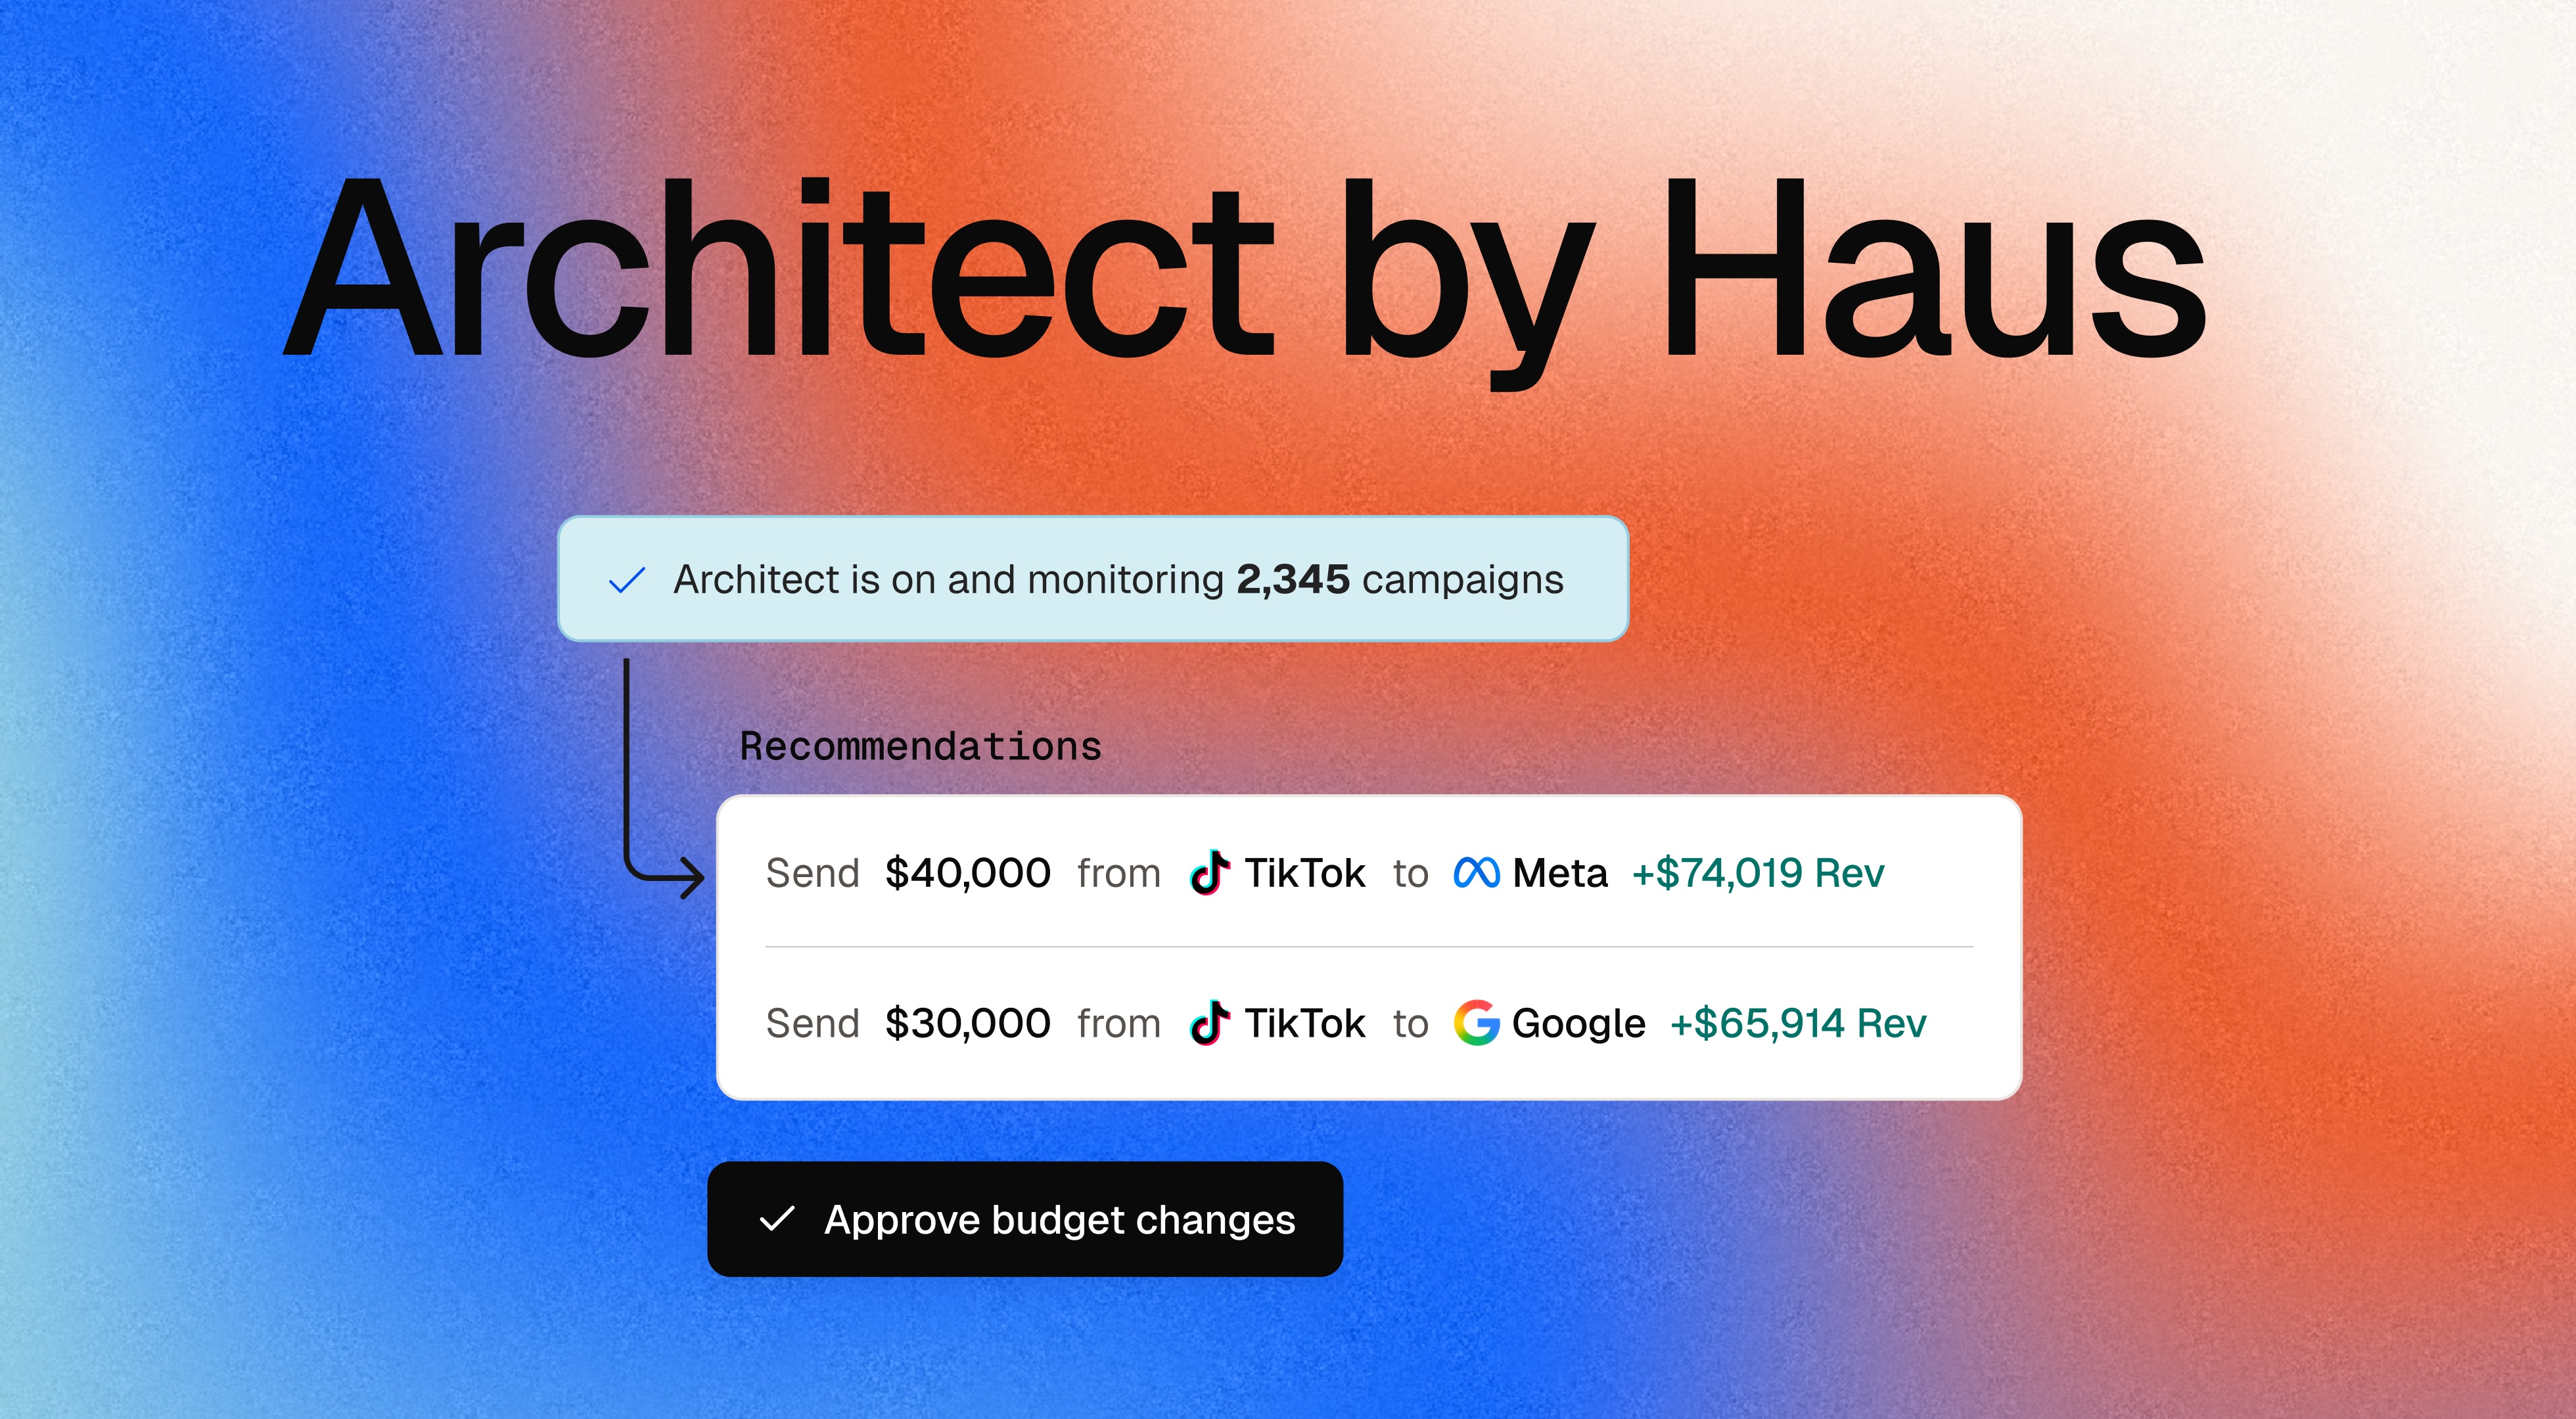
Ideally, you aren’t just getting data. You’re also getting some sort of decisioning mechanism. This is something new we can do with AI, and it’s the foundation of an unbiased partner. It settles those difficult moments when you have conflicting signals on your dashboards. (At Haus, we call this Architect.)
There are many decisions on the path to an efficient media budget. There’s determining annual budgets with finance. Defining per-period goals. And of course allocating budget over time. The ideal MMM in 2026 works in lockstep with these decisions, breaking down your job into manageable parts. This system tells you what you need to do tomorrow to get your business where you want it to go.
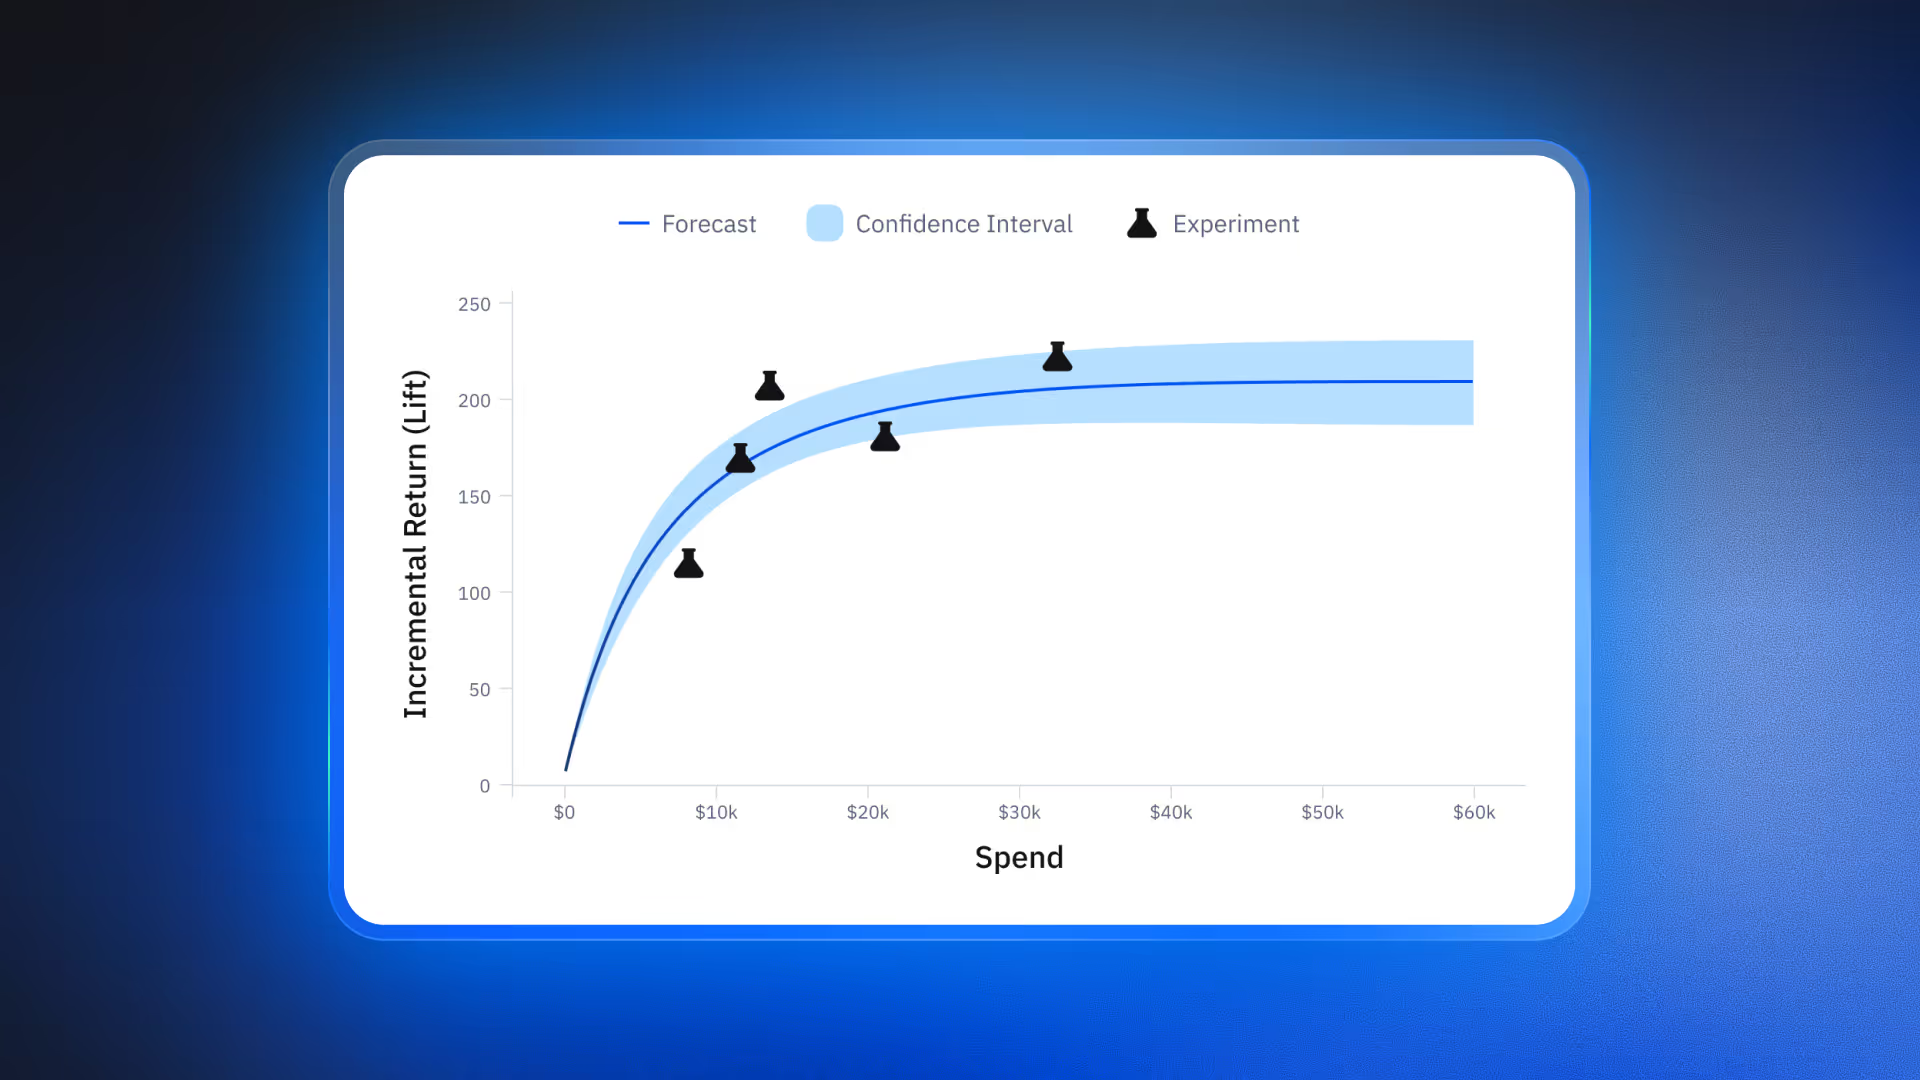
I don’t think the future of MMM is about choosing between experiments, observational data, and modeling. It’s about combining them correctly. The company owns its data, infrastructure, institutional knowledge, and interfaces. Specialized science supports experimentation, validation, and methodological integrity with the aim of supporting better decision-making.
You also get something important with a partner running an integrated system: innovation. This is underrated. Every partner will tell you they provide “ample support.” But working with a team that has hundreds of people working behind the scenes and a proven track record of driving innovation that supports decision-making is a benefit that doesn’t show up as a line item on a contract
The ideal MMM doesn’t just report what happened. It connects signals, recommends what to do next, breaks that plan into weekly actions, improves, and reports back to you to tell you how much your changes contributed to the business.
Subscribe to our newsletter
Article tags
Article authors
Before joining Haus as Senior Applied Scientist, Ittai Shacham earned his econometrics PhD at Tilburg University. After that, he was a senior researcher at Meta, where he built some of the company’s most sophisticated internal causal modeling tools. Learn more about his path to Haus and his time on the Haus Science team.